What Are BrandRank.ai Normalization Transformation Rules and Why Do They Matter for Your Brand Data?
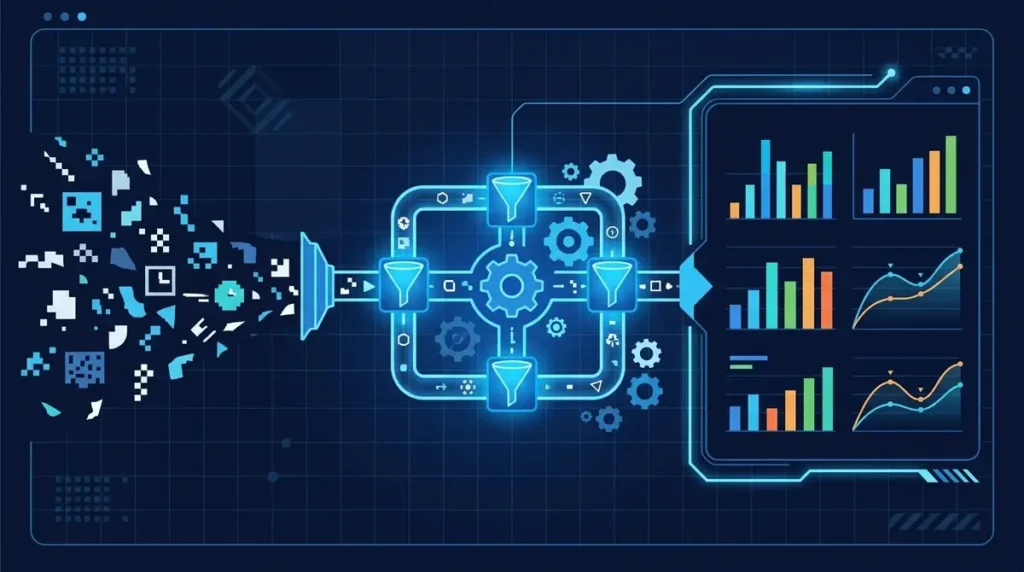
Your brand analytics dashboard looks clean, but the data feeding it often arrives fragmented, duplicated, and riddled with inconsistencies. These hidden errors quietly distort every metric you trust. Understanding brandrank.ai normalization transformation rules solves this problem directly. These rules strip noise, enforce formatting standards, and merge scattered records into a single reliable source of truth for your team.
What Are BrandRank.ai Normalization Transformation Rules?
Brandrank.ai normalization transformation rules are automated instructions that clean, reformat, and unify raw brand data before it enters your analytics pipeline. Every data point your platform collects — from social mentions to search volume figures — passes through these rules to guarantee accuracy and consistency.
Think of these rules as a quality control checkpoint standing between chaos and clarity. They catch misspelled brand names, merge duplicate entries, and convert varying date formats into one standard. Without this protective layer, your reports would reflect noise instead of reality.
Why Does Raw Brand Data Need Normalization Before Analysis?
Raw brand data streams in from dozens of sources: social media APIs, web scrapers, CRM exports, and advertising platforms. Each source formats information differently. One channel might list your brand as “BrandRank AI,” another as “brandrank.ai,” and a third as “Brand Rank.”
These surface-level variations create phantom duplicates that inflate your metrics and mislead your team. Normalization collapses every variation into one canonical entity so your numbers reflect actual performance. The National Institute of Standards and Technology (NIST) confirms that organizations sacrifice significant decision-making accuracy when they skip data quality preprocessing [1].
How Does BrandRank.ai Process and Transform Incoming Data?
When data enters the BrandRank.ai platform, it flows through a multi-stage transformation pipeline. The first stage identifies the data type — text, numeric, categorical, or temporal. The second stage applies the appropriate brandrank.ai normalization transformation rules based on that specific classification.
For text fields, the system trims whitespace, corrects capitalization, and maps synonyms to your preferred terms. For numeric fields, it standardizes measurement units and scales values to a common range. This layered approach ensures every data type receives the precise treatment it requires.
What Core Components Make Up the Transformation Rule Engine?
The transformation engine inside BrandRank.ai relies on four core components working in sequence:
- Pattern Matching Rules: These scan incoming text for known variations of your brand name, product names, and campaign tags.
- Mapping Tables: Pre-built dictionaries that convert shorthand, abbreviations, and regional spellings into your canonical terms.
- Conditional Logic Blocks: If-then statements that apply different rules depending on the data source or field type.
- Validation Gates: Final checkpoints that flag any record failing to meet your quality thresholds before it reaches your dashboard.
Each component handles a distinct job, and together they form the backbone of brandrank.ai normalization transformation rules. You can adjust any single component independently without disrupting the rest of the pipeline.
Which Data Cleaning Rules Remove Noise From Brand Signals?
Noise in brand data takes many damaging forms. Bot-generated social mentions, duplicate press release pickups, and tracking pixel misfires all inject false signals into your analytics.
BrandRank.ai addresses these issues through dedicated cleaning rules:
- Bot Filtering: Identifies and removes engagement metrics generated by automated accounts using behavioral pattern analysis.
- Deduplication Logic: Detects identical or near-identical records within a configurable time window and merges them into a single entry.
- Outlier Flagging: Marks data points that fall outside statistically expected ranges and queues them for manual review.
- Source Weighting: Assigns reliability scores to each data channel so high-quality sources carry more influence in your final metrics.
These cleaning rules run automatically on every ingestion cycle. You set the sensitivity thresholds once, and the system handles the heavy lifting from that point forward.
How Does Entity Resolution Work Inside BrandRank.ai?
Entity resolution determines whether two data records refer to the same real-world object. In brand analytics, this means figuring out whether “BrandRank,” “BrandRank.ai,” and “Brand Rank AI” all point to your company.
The platform uses a combination of string similarity algorithms and contextual signals to make these determinations. It compares character overlap, word order, and surrounding metadata like domain names and industry classification tags. When the confidence score exceeds your preset threshold, the system merges the records automatically.
This capability sits at the heart of brandrank.ai normalization transformation rules because unresolved entities create the most damaging data errors. A single brand split across three entity profiles can make your market share appear one-third of its actual size.
What Standardization Rules Keep Brand Metrics Consistent?
Standardization rules enforce uniform formatting across every field in your dataset. Without them, your team wastes hours reconciling conflicting numbers during every reporting cycle.
Key standardization functions include:
- Date Unification: Converts all timestamps to ISO 8601 format regardless of the source region or original convention.
- Currency Normalization: Translates revenue figures into your base currency using real-time exchange rate feeds.
- Metric Scaling: Converts percentages, ratios, and raw counts into a consistent measurement framework your team can compare directly.
- Taxonomy Alignment: Maps disparate category labels from different platforms to your internal brand taxonomy.
ISO 8000, the international standard for data quality, emphasizes that consistent formatting reduces downstream processing errors by a measurable margin [2]. BrandRank.ai builds these principles directly into its rule engine architecture.
How Do You Configure Custom Transformation Rules?
BrandRank.ai ships with a comprehensive library of pre-built rules, but your brand’s data landscape likely demands custom configurations. The platform provides a visual rule builder that lets you define new logic without writing a single line of code.
Start by selecting the data field you want to transform. Choose the operation type — replace, merge, split, calculate, or filter. Then set the conditions under which the rule triggers and define the expected output format.
For advanced users, BrandRank.ai also supports regex-based pattern matching and custom scripting for complex brandrank.ai normalization transformation rules. You can test every new rule against a sample dataset before deploying it to your live production pipeline.
What Mistakes Sabotage Your Normalization Setup?
Even well-designed normalization pipelines break when teams make avoidable errors. Here are the most common pitfalls that undermine data quality:
- Over-Aggressive Deduplication: Merging records that look similar but actually represent distinct entities, such as two different products with nearly identical names.
- Ignoring Source Context: Applying the same rules to social media data and financial data, even though these sources have fundamentally different structures and reliability levels.
- Skipping Validation Gates: Pushing transformed data to dashboards without a final quality check, allowing edge-case errors to slip through undetected.
- Failing to Update Rules: Keeping outdated mapping tables that no longer reflect your current brand architecture, product lineup, or campaign naming conventions.
These mistakes degrade the effectiveness of brandrank.ai normalization transformation rules and reintroduce the very inconsistencies you set out to eliminate. Audit your rule configurations quarterly to catch drift before it compounds.
How Can You Measure Normalization Impact on Brand Analytics?
You need concrete proof that your normalization efforts actually improve data quality. BrandRank.ai provides built-in quality scorecards that track key indicators before and after transformation.
Monitor these metrics closely:
- Duplicate Rate: The percentage of records flagged as duplicates during each ingestion cycle. A declining rate signals effective deduplication.
- Entity Match Confidence: The average confidence score of entity resolution decisions. Higher scores mean your rules correctly identify and merge brand mentions.
- Field Completeness: The proportion of records with all required fields populated after transformation runs.
- Anomaly Frequency: The number of data points flagged as outliers post-normalization compared to your baseline.
Google’s Search Central documentation reinforces that structured, high-quality data produces more reliable outputs across all analytical systems [3]. Track these indicators monthly to demonstrate clear ROI to your stakeholders.
How Does BrandRank.ai Compare to Manual Data Workflows?
Manual data transformation requires analysts to open spreadsheets, write formulas, and manually reconcile conflicts across dozens of files. This process eats hours every week and introduces human error at every single step.
BrandRank.ai automates the entire workflow end to end. Once you configure your brandrank.ai normalization transformation rules, the platform applies them to every new data batch in real time. Your analysts shift from data janitors to strategic thinkers who actually interpret insights.
| Feature | Manual Workflow | BrandRank.ai Automated Rules |
|---|---|---|
| Processing Speed | Hours per dataset | Seconds per dataset |
| Error Rate | 5–15% typical | Below 1% with validation gates |
| Scalability | Breaks past 10K records | Handles millions of records |
| Consistency | Varies by analyst | Identical output every run |
| Update Frequency | Weekly or monthly | Real-time on ingestion |
| Audit Trail | Rarely maintained | Full version history logged |
| Custom Rule Support | Limited to spreadsheet formulas | Regex, scripts, visual builder |
| Entity Resolution | Manual matching | AI-powered auto-merge |
The efficiency gap speaks for itself. Teams that switch from manual processes to automated normalization typically recover 15 to 20 hours per analyst per month.
What Steps Should You Take Next to Optimize Your Pipeline?
Start by auditing your current data sources and listing every inconsistency you encounter across channels. Map these problems to specific rule types — cleaning, deduplication, standardization, or entity resolution.
Open the BrandRank.ai rule builder and tackle your highest-impact issue first. Deploy one rule, measure the quality improvement, and iterate from there. Layering rules gradually prevents cascading errors and gives your team time to adapt to the new data standards.
Your brand data deserves better than guesswork and manual patchwork. Every inconsistent record, every duplicate entry, and every misformatted metric pulls your strategy in the wrong direction. The brandrank.ai normalization transformation rules framework gives you the tools to fix these problems permanently — not with temporary band-aids, but with systematic, automated precision that scales with your business.
Open your BrandRank.ai dashboard today, run a full data quality audit, and build your first custom transformation rule before the end of the week. Your future reports will reflect reality, and your team will finally trust the numbers they see on screen.
References
[1] National Institute of Standards and Technology (NIST). Data Quality Framework and Guidelines. nist.gov
[2] International Organization for Standardization. ISO 8000: Data Quality — Master Data. iso.org
[3] Google Search Central. Structured Data and Data Quality Guidelines. developers.google.com